My research focuses on making language-model generation reliable and efficient, spanning the following topics:
See Google Scholar for the full list.

Prefix-Denoising Consistency: Test-Time Verification for Diffusion Language Models
Y. Ichihara, N. Iwase, M. A. Quamar, J. Komiyama.
Arxiv, 2026
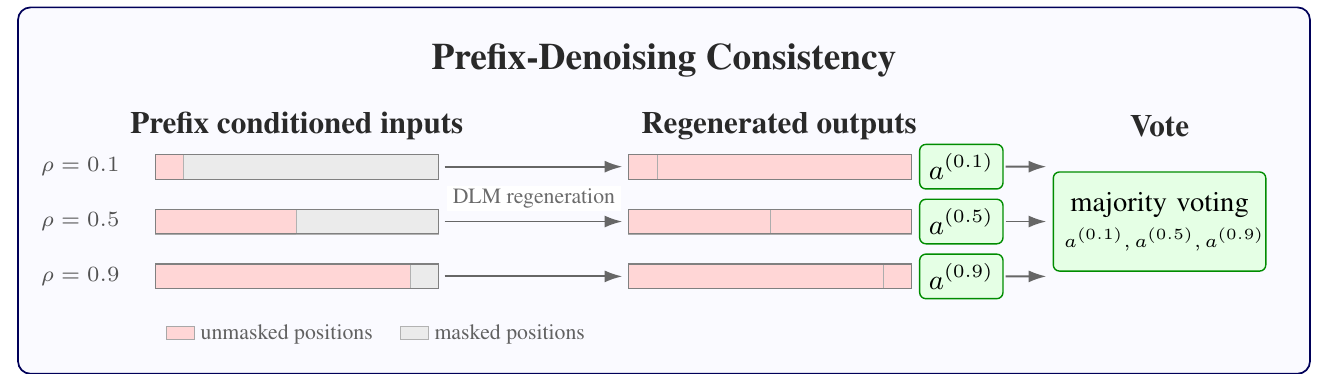
We verify diffusion-language-model outputs by keeping different prefixes, regenerating the masked suffix, and voting over the resulting answers.
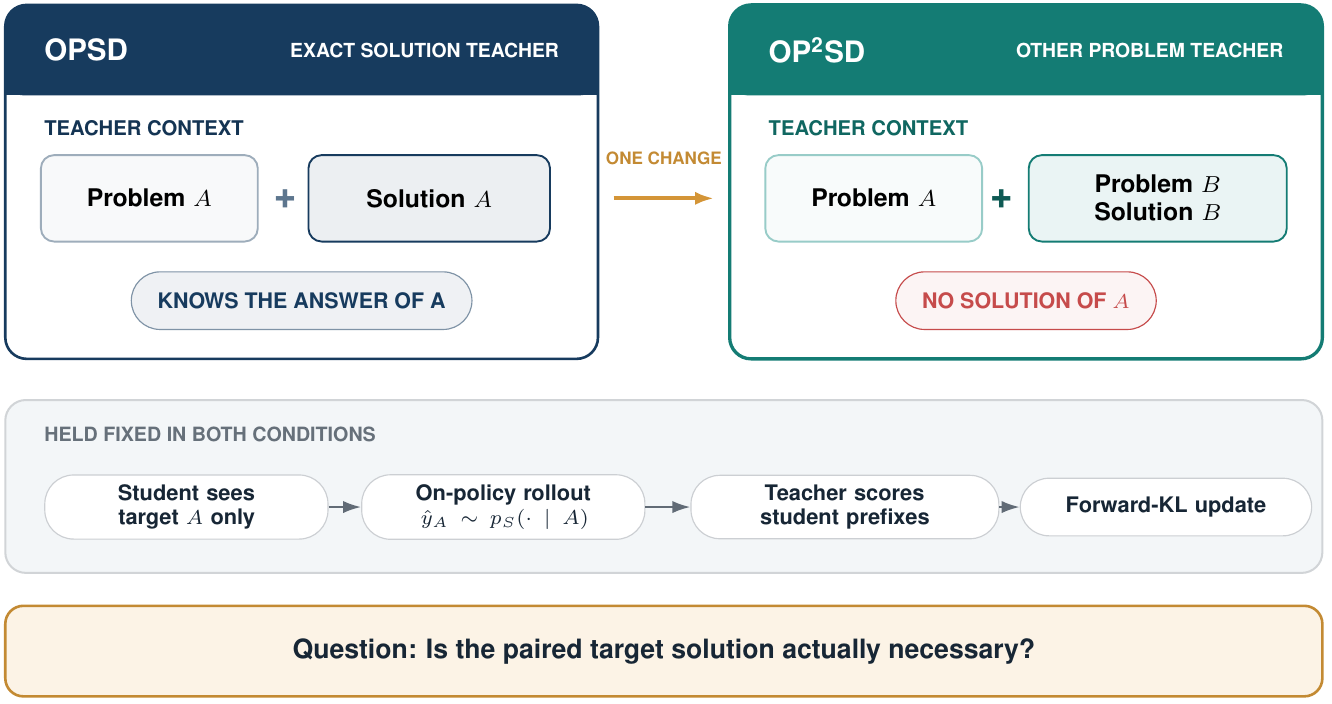
Privileged Solutions or Context-Induced Teacher Behavior? Dissecting On-Policy Self-Distillation
Y. Ichihara, N. Iwase, M. A. Quamar, J. Komiyama.
On-policy self-distillation still works when the teacher sees a solution to a different problem, showing that context-induced teacher behavior is a key part of the signal.

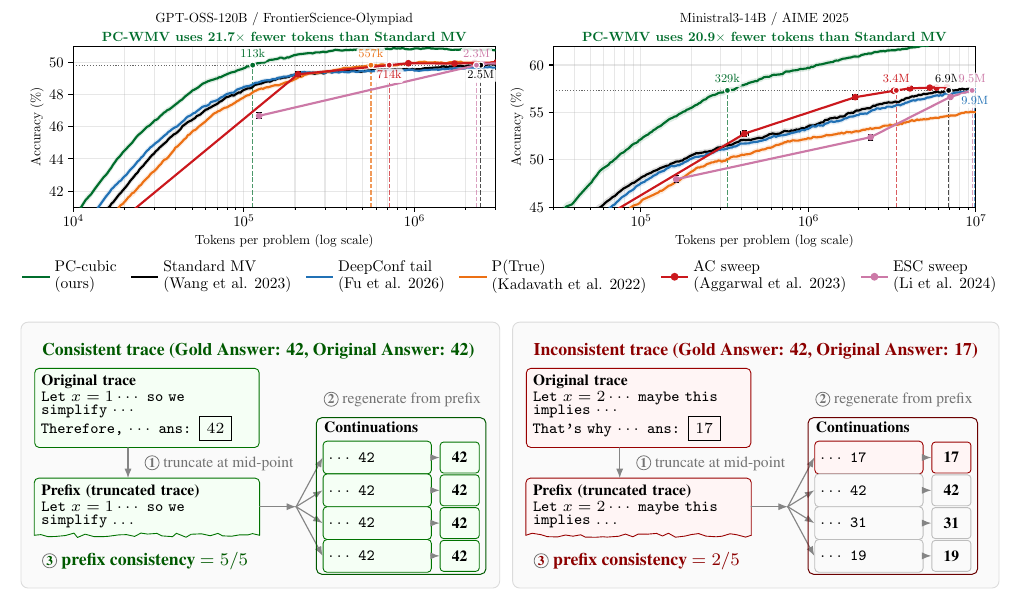
Reliable Chain-of-Thought via Prefix Consistency
N. Iwase, Y. Ichihara, M. A. Quamar, J. Komiyama.
We estimate the reliability of a chain-of-thought by truncating it and checking whether regenerated continuations recover the same answer.

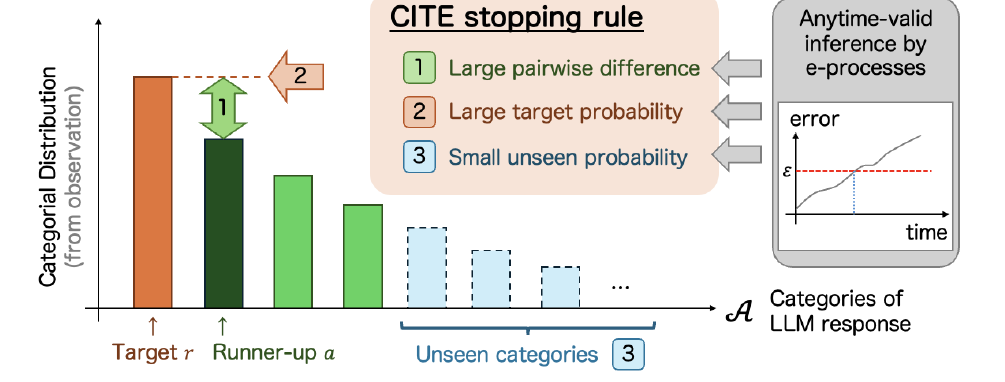
CITE: Anytime-Valid Statistical Inference in LLM Self-Consistency
H. Ota, N. Iwase, Y. Ichihara, J. Komiyama, M. Imaizumi.
Arxiv, NeurIPS 2026
Anytime-valid certification that a response is the unique mode of an LLM's answer distribution, without assuming a known set of possible answers.

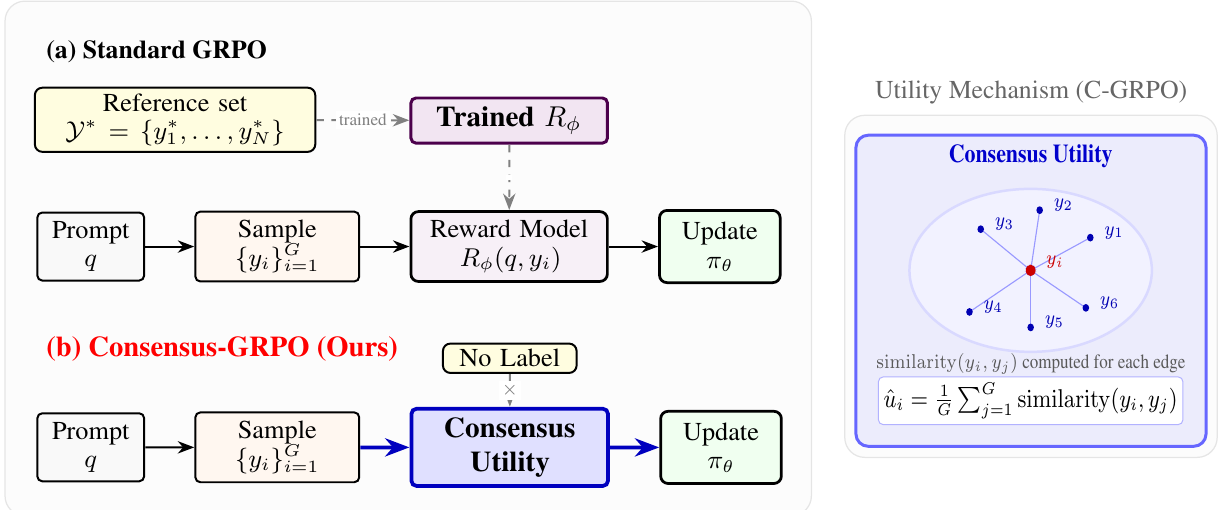
Consensus Group Relative Policy Optimization for Text Generation
Y. Ichihara, Y. Jinnai, K. Ariu, E. Uchibe.
We distill Minimum Bayes Risk decoding into GRPO training, matching MBR quality without its inference-time overhead.

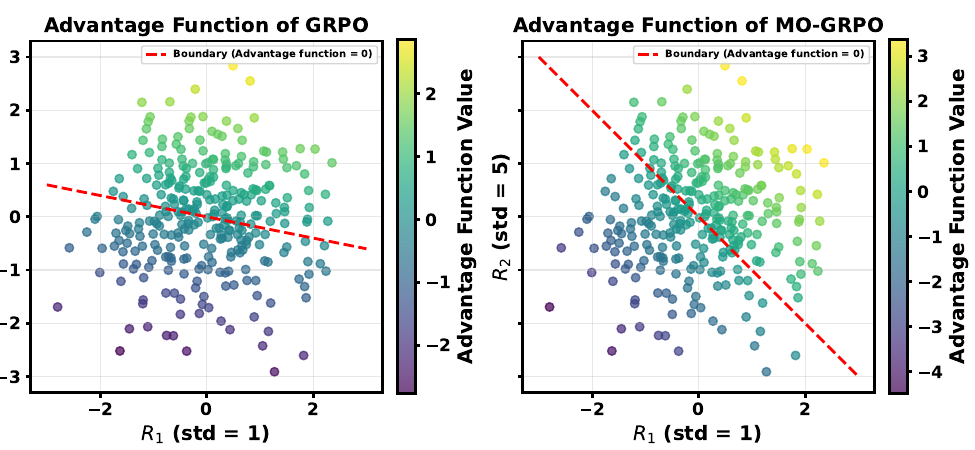
MO-GRPO: Mitigating Reward Hacking of Group Relative Policy Optimization on Multi-Objective Problems
Y. Ichihara, Y. Jinnai, T. Morimura, M. Sakamoto, R. Mitsuhashi, E. Uchibe.
Arxiv / Code / Guide, TACL 2026
Variance-based reward normalization lets multi-objective GRPO balance objectives without manual scale tuning, mitigating reward hacking.

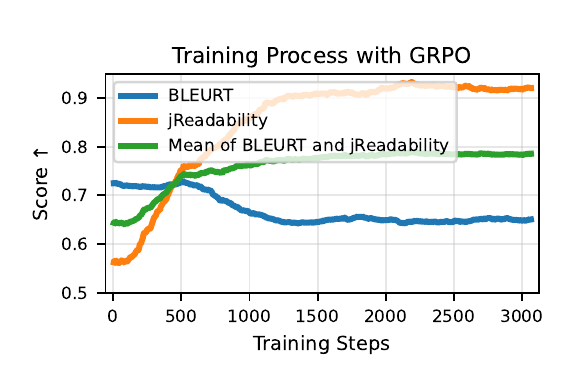
Auto-Weighted Group Relative Preference Optimization for Multi-Objective Text Generation Tasks
Y. Ichihara, Y. Jinnai.
Paper / Code, EMNLP 2025 Industry Track
We adjust multiple reward weights automatically according to each objective's learning progress.

Theoretical Guarantees for Minimum Bayes Risk Decoding
Y. Ichihara, Y. Jinnai, K. Ariu, T. Morimura, E. Uchibe.
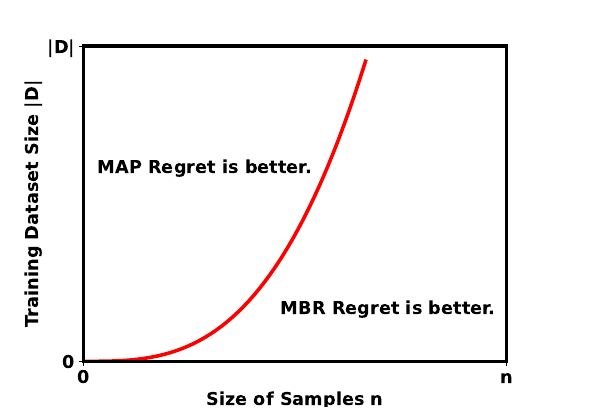
MBR decoding approaches the optimal solution at a rate of O(n−1/2), and can converge faster than MAP decoding.

Evaluation of Best-of-N Sampling Strategies for Language Model Alignment
Y. Ichihara, Y. Jinnai, T. Morimura, K. Abe, K. Ariu, M. Sakamoto, E. Uchibe.
Paper, TMLR 2025
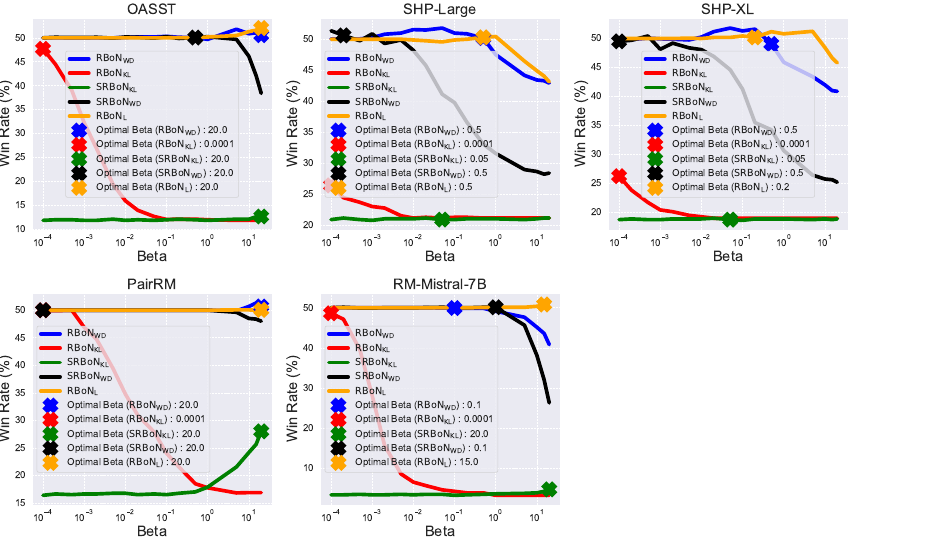
We frame regularized Best-of-N sampling as robust optimization against proxy-reward errors and introduce Stochastic RBoN to reduce reward hacking.

A Policy Gradient Primal-Dual Algorithm for Constrained MDPs with Uniform PAC Guarantees
T. Kitamura, T. Kozuno, M. Kato, Y. Ichihara, S. Nishimori, A. Sannai, S. Sonoda, W. Kumagai, Y. Matsuo.
Arxiv, RLSW 2024 Workshop
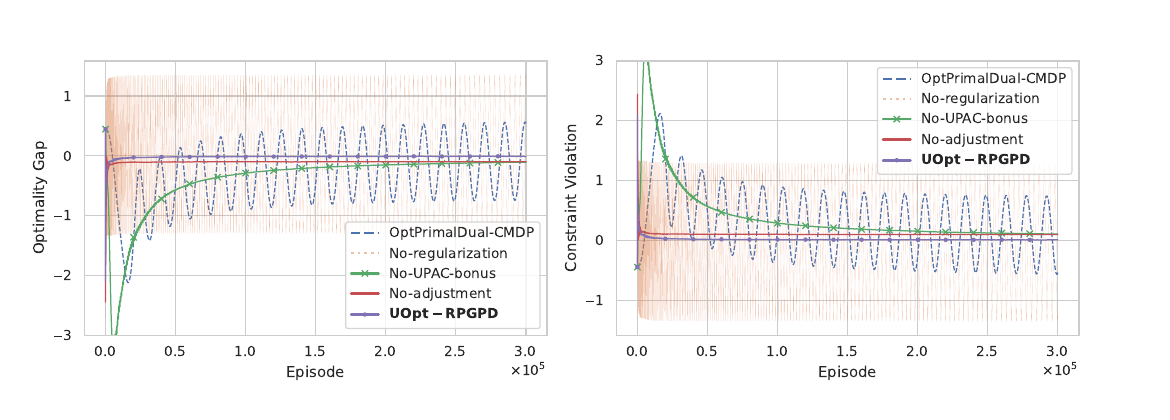
A policy-gradient primal-dual algorithm for online constrained MDPs with Uniform-PAC guarantees.